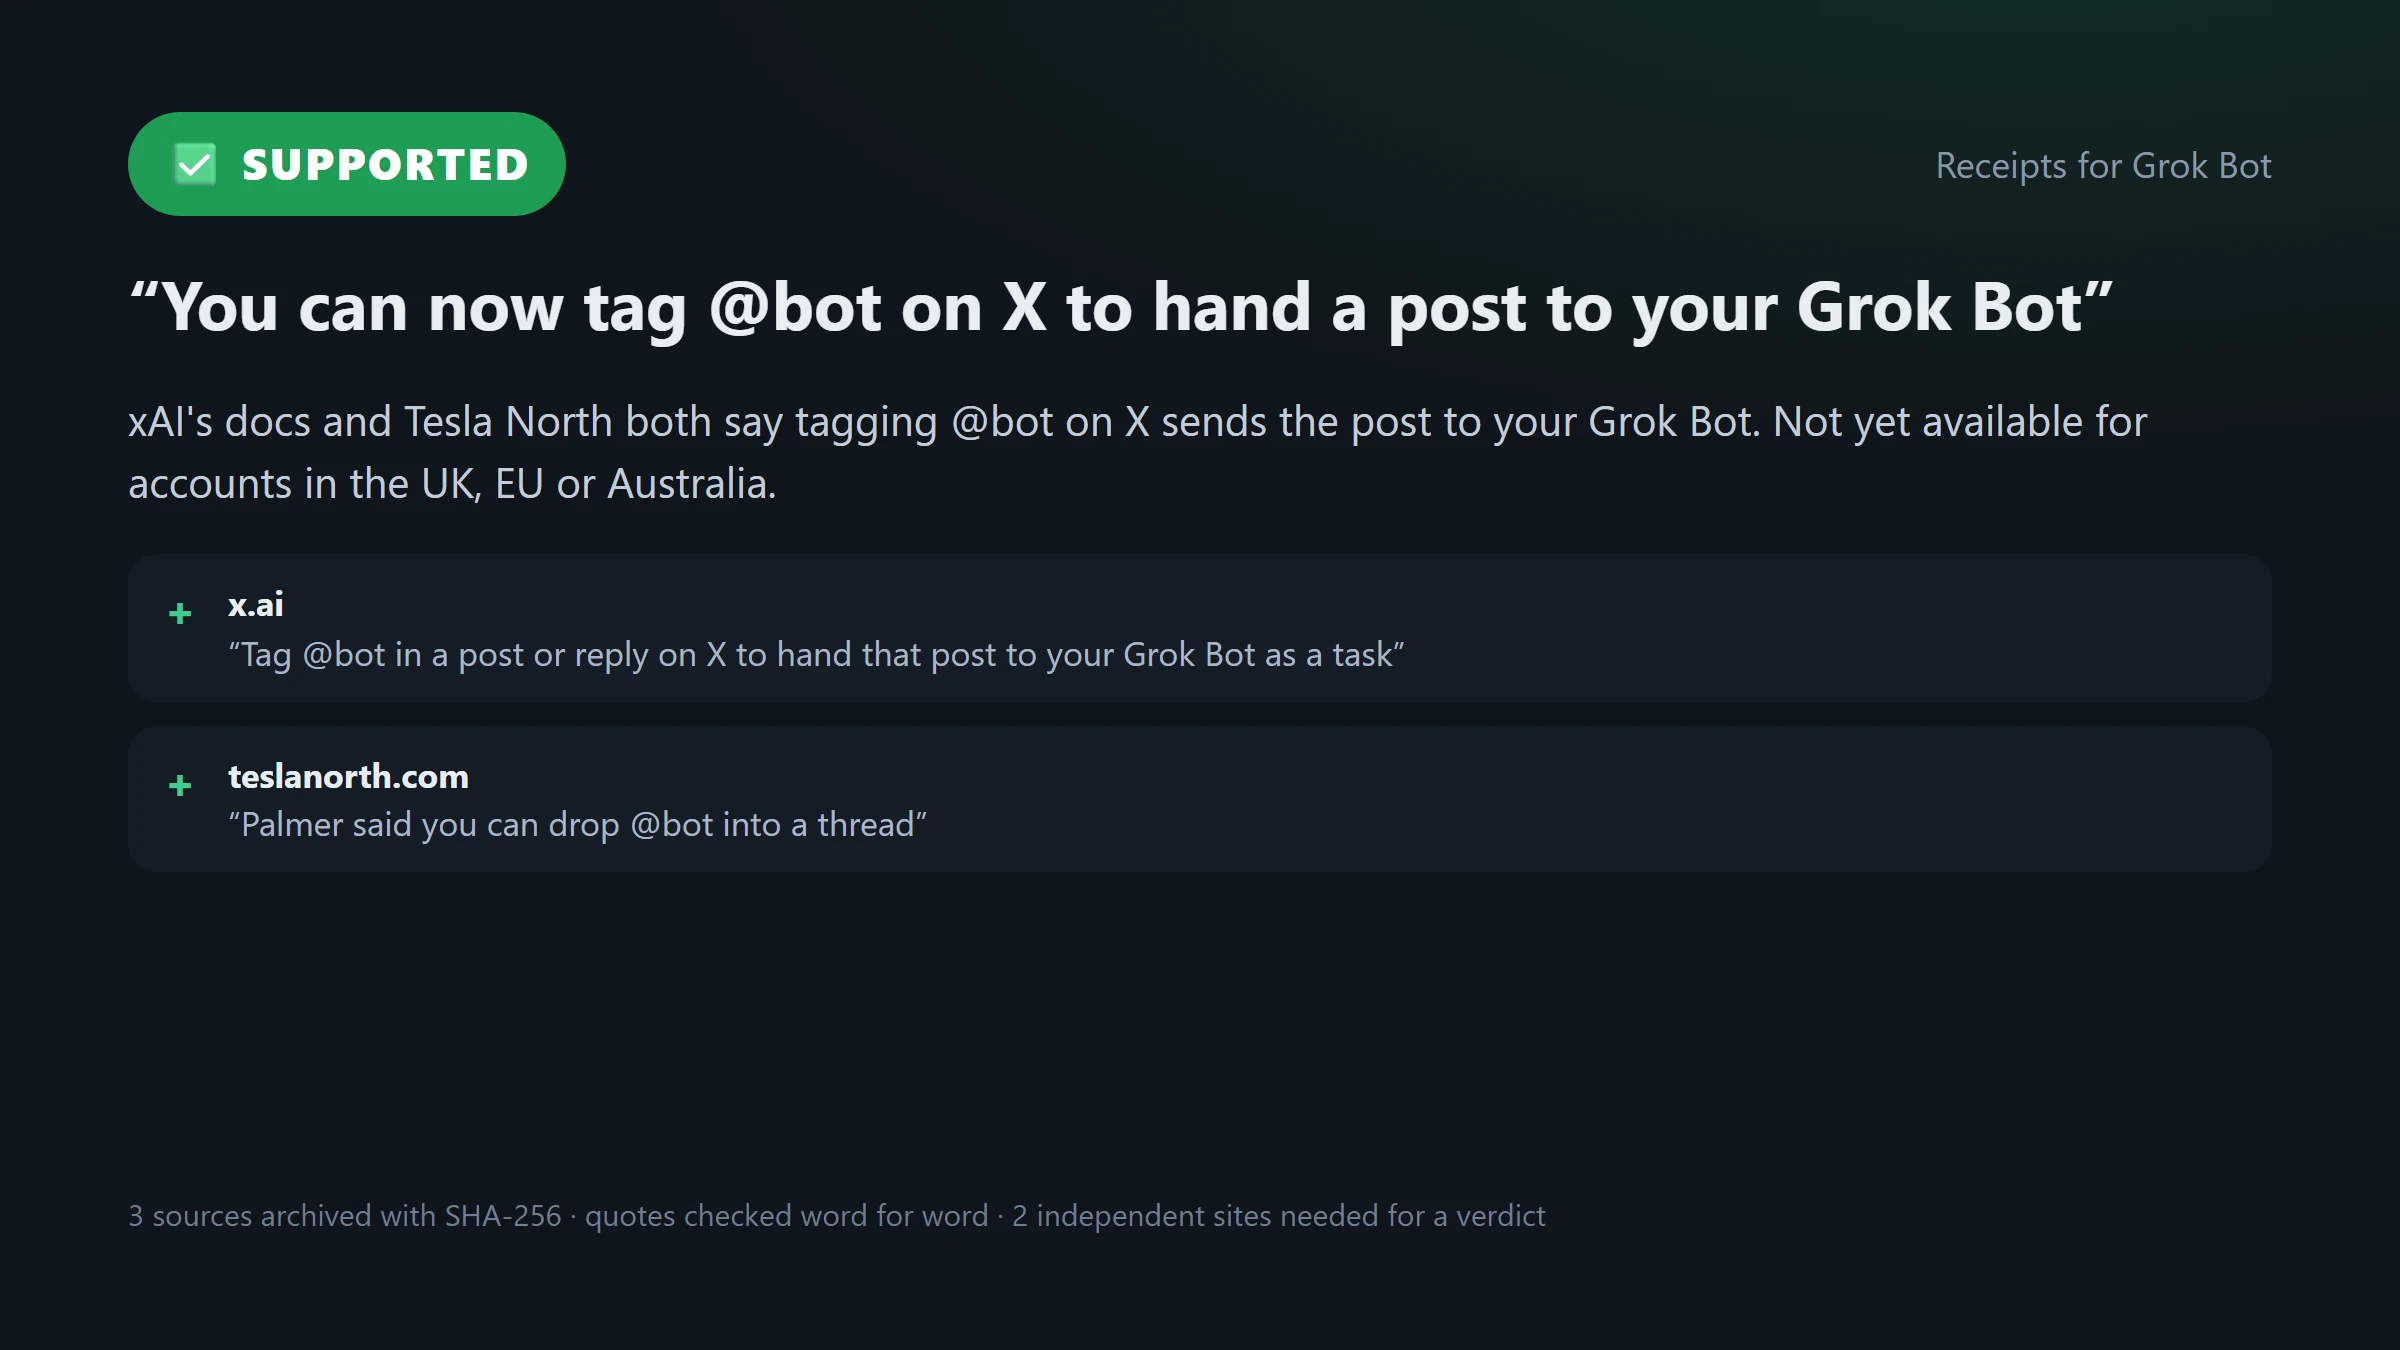
Receipts is a fact-check skill for Grok Bot. Tag your Bot on a post, and it archives every source, checks each quote word for word, and refuses to call the claim supported until two independent sites back it. It is free, MIT-licensed and on GitHub.
Claude researched the idea, built it, tested it and ran it on a real claim in about ten minutes, and the whole session was screen-recorded. You can watch the 42-second cut.
Why build it
Replying "is this true?" to Grok under a post has become how a lot of people check things on X. The answers come back confident whether they are right or wrong. Al Jazeera traced hours of argument on X back to a wrong Grok answer about National Guard photos, and BOOM and Alt News have collected more.
This week Grok Bot, xAI's hosted agent with its own cloud computer, started taking tasks from X: reply to a post with @bot and your own Bot picks it up. That Bot has a terminal, so it can run a tool with rules it has to follow.
What the rules are
The Bot does the judging: it turns the post into one claim, searches for sources and decides what each one says. The receipts tool does the parts where a confident mistake causes damage.
- Every source is archived. Crawl4AI opens each page in a headless browser and saves it as Markdown with a SHA-256 hash and the time it was read. A deleted post or an edited article leaves the evidence intact.
- Quotes are checked word for word. When the Bot says a source supports or contradicts the claim, it has to quote the source. The tool rejects any quote it can't find in the archived copy.
- Two independent sites, or no verdict. "Supported" and "contradicted" need quotes from two different sites. Two links from one publisher count once, and the site the claim was posted on never counts for itself.
- Any disagreement means disputed. One contradicting source blocks a clean verdict.
- Nothing posts on its own. You get a report, a verdict card and a draft reply that fits X's 280 characters. You decide whether it goes out.
The live test
The first real claim was about Grok Bot itself: "You can now tag @bot on X to hand a post to your Grok Bot."
With only xAI's documentation quoted, the tool refused: one site isn't enough. Once a quote from Tesla North's write-up went in, "supported" was allowed. X's own help page was archived too but didn't count, because it sits on the same site as the original post.
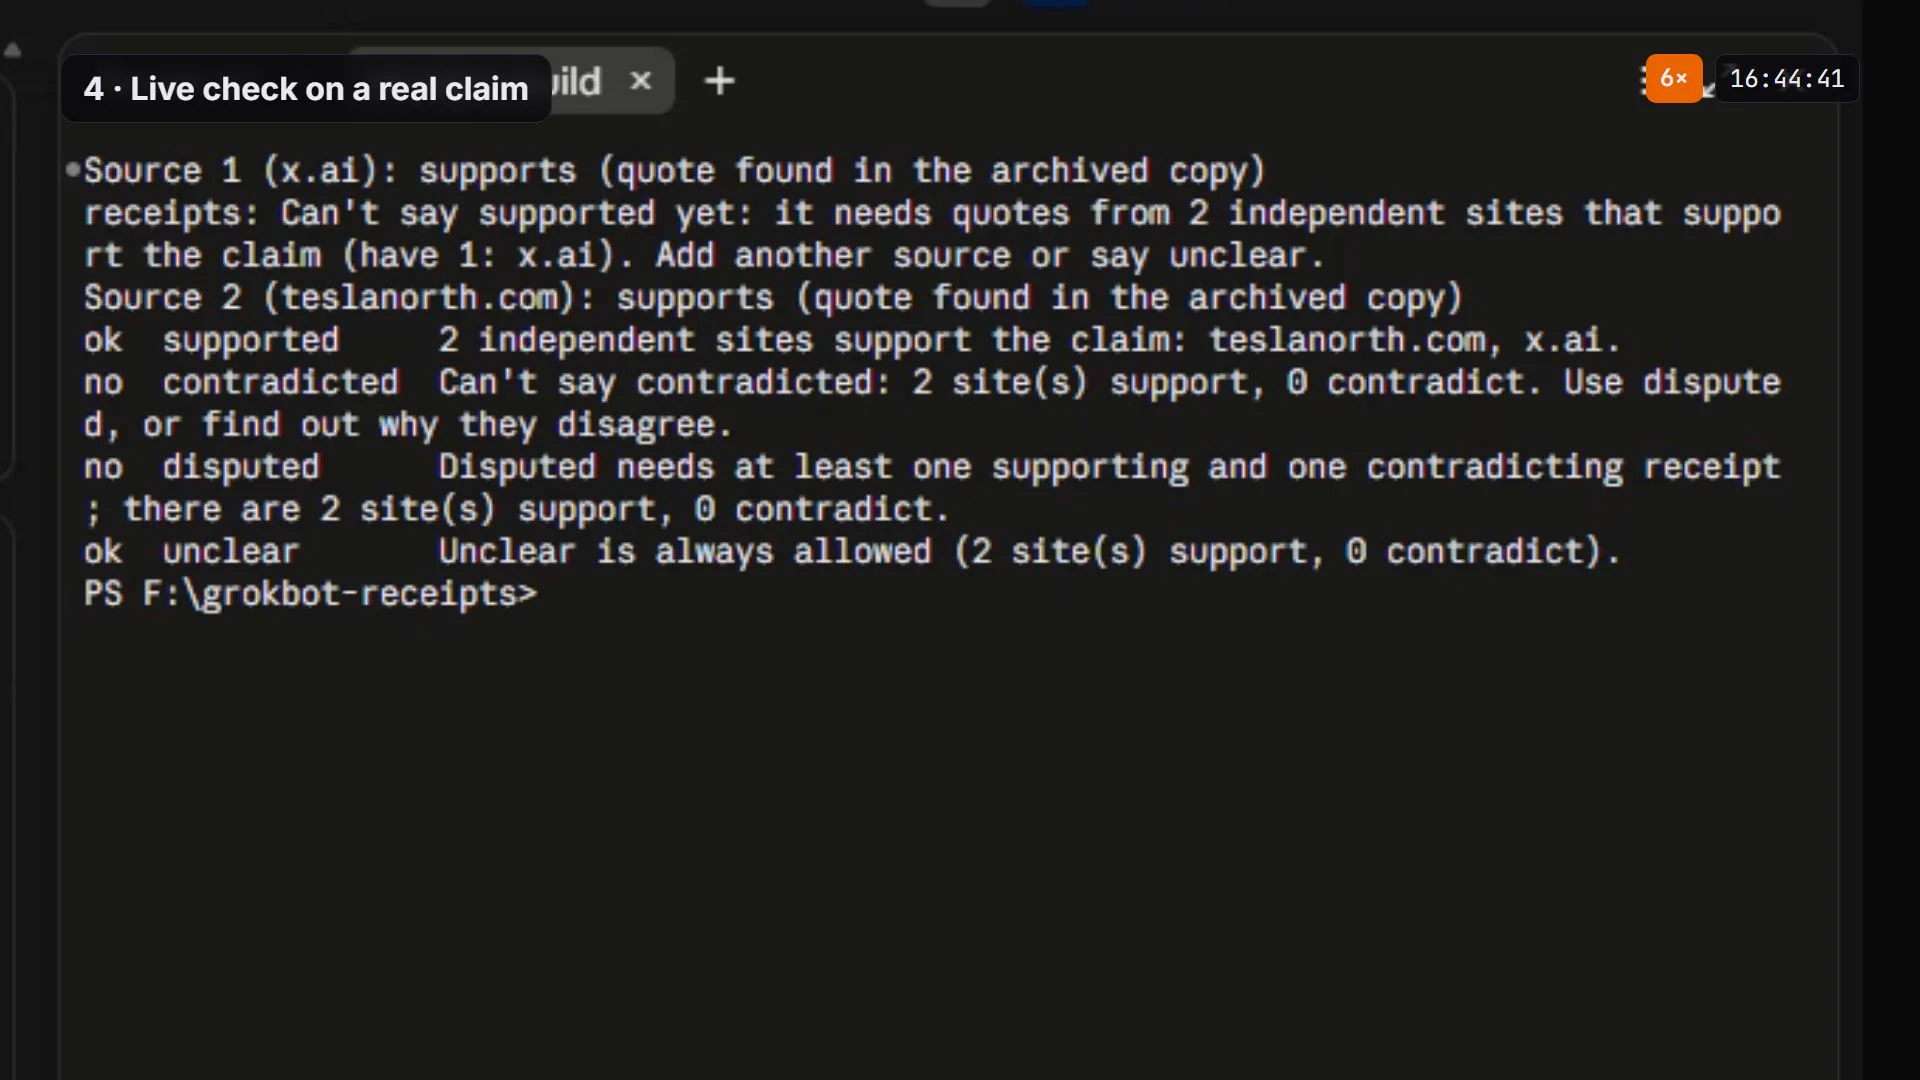
The run turned up a detail worth knowing: Tesla North says you need the X plugin installed for @bot to work, while xAI's docs call it optional. The card records the claim as supported and notes that tagging isn't available yet for accounts in the UK, EU or Australia.
How it was built
Claude started from the brief "find what Grok Bot users want and build it from RepoQuarry tools". It read xAI's Grok Bot docs, picked Crawl4AI from the RepoQuarry catalogue for fetching pages, and wrote the tool in Python with no other runtime dependencies. Passage ranking uses BM25 in plain Python, so the same page always gives the same answer.
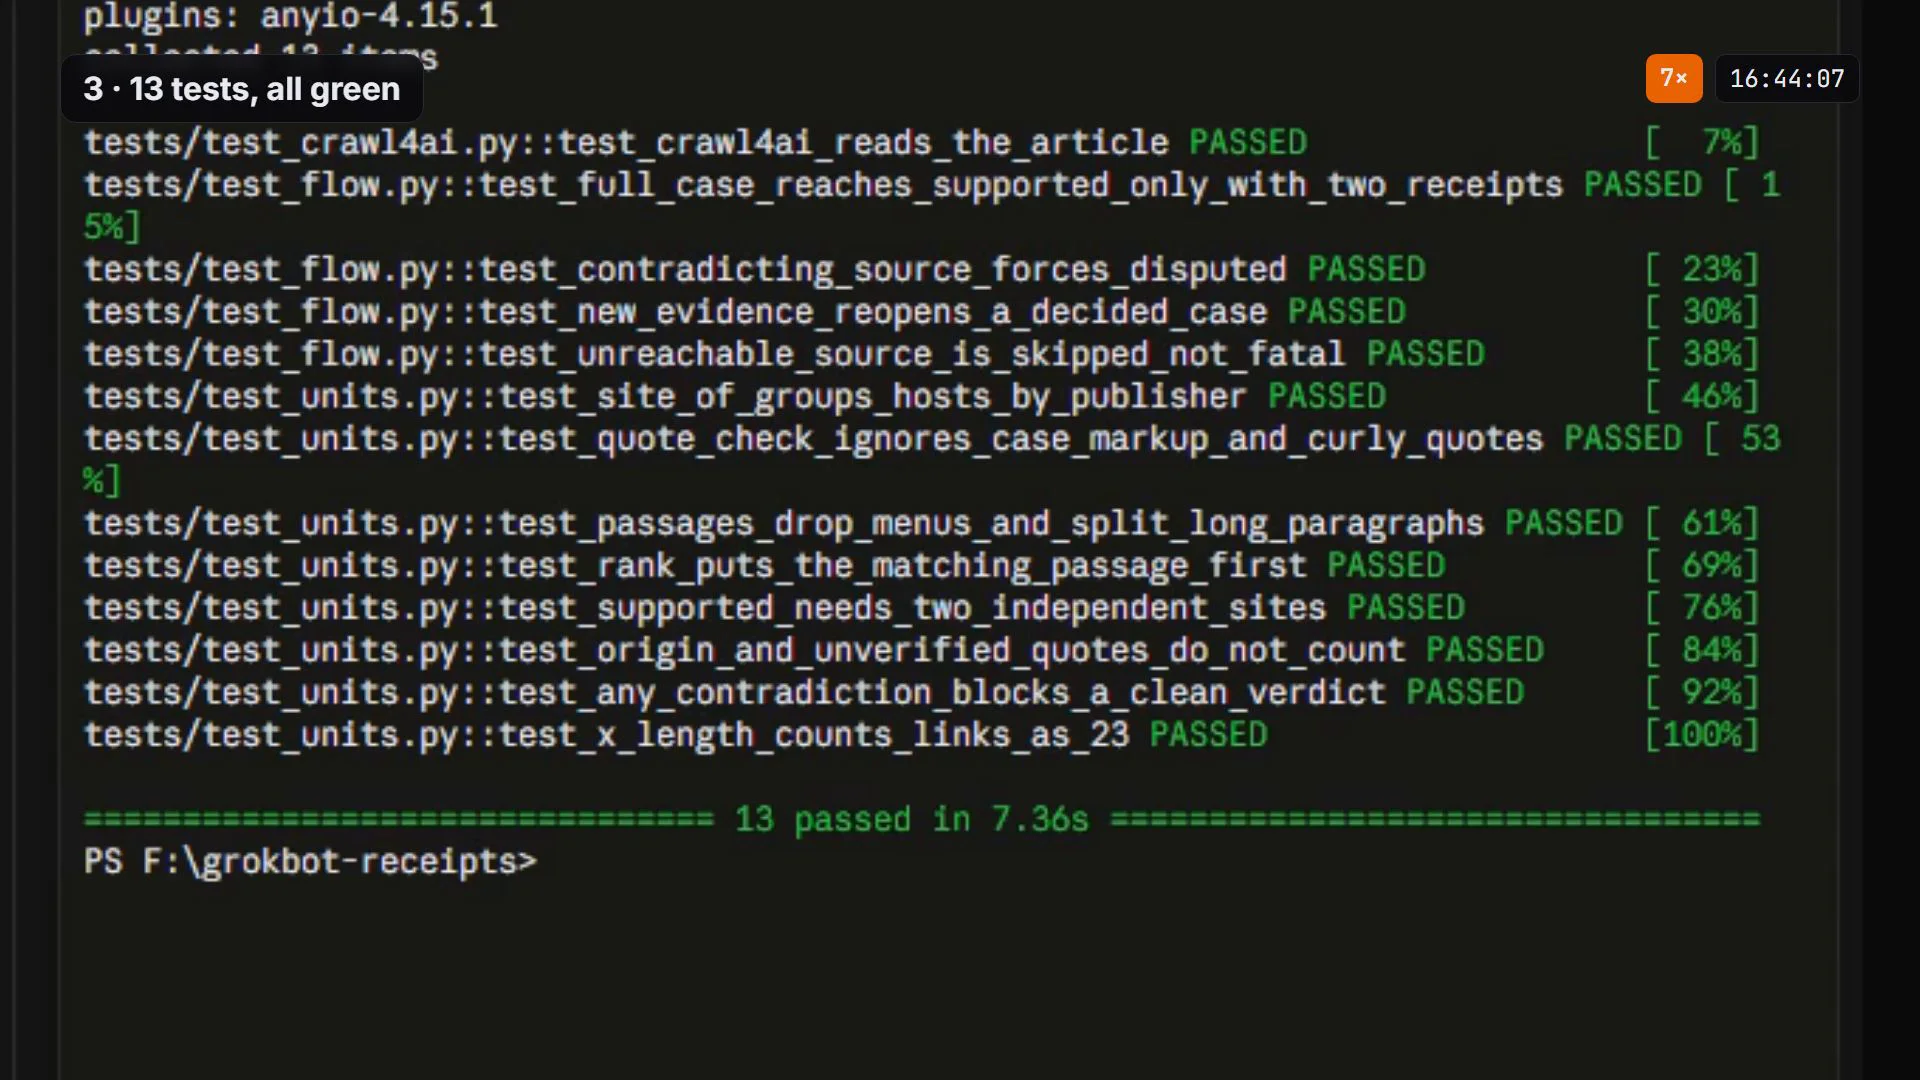
Thirteen tests passed on the first run, including a real Crawl4AI browser fetch against local stand-in news sites. A fourteenth was added after the live check caught headings running into paragraphs on some pages. CI runs all of them on Python 3.10 and 3.13.
What isn't tested yet
The command-line tool is tested end to end. The Grok Bot skill is written to xAI's documented behaviour but hasn't run on a live Grok Bot plan, and @bot tagging itself isn't available for UK-based X accounts. If you run it on your Bot, an issue on the repo with what happened would help.
Two sites can still both be wrong, or both copy the same wire story. The rule raises the bar for a confident answer. It doesn't make the answer true, which is why the report shows every quote and hash.
Try it
Install the tool:
pip install "grokbot-receipts[crawl4ai] @ git+https://github.com/Obiwayne/grokbot-receipts"
crawl4ai-setup
Then paste the skill into a Grok Bot chat and save it. The build log covers every decision and what was checked.
This product includes software developed by UncleCode (https://x.com/unclecode) as part of the Crawl4AI project (https://github.com/unclecode/crawl4ai).